fqxv info
Print container metadata and per-stream compressed sizes for a .fqxv archive.
Usage
fqxv info <INPUTS>... [--stats] [--tsv | --json]
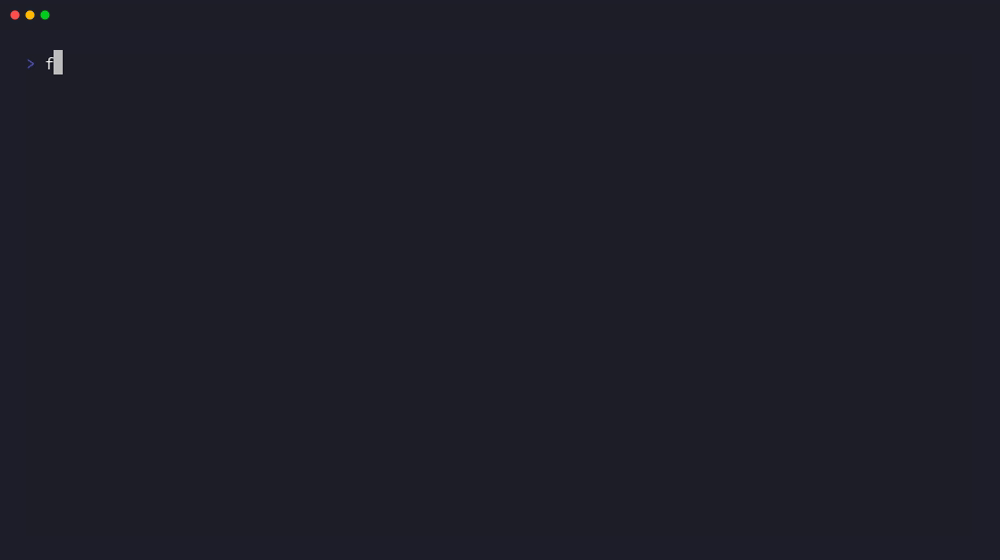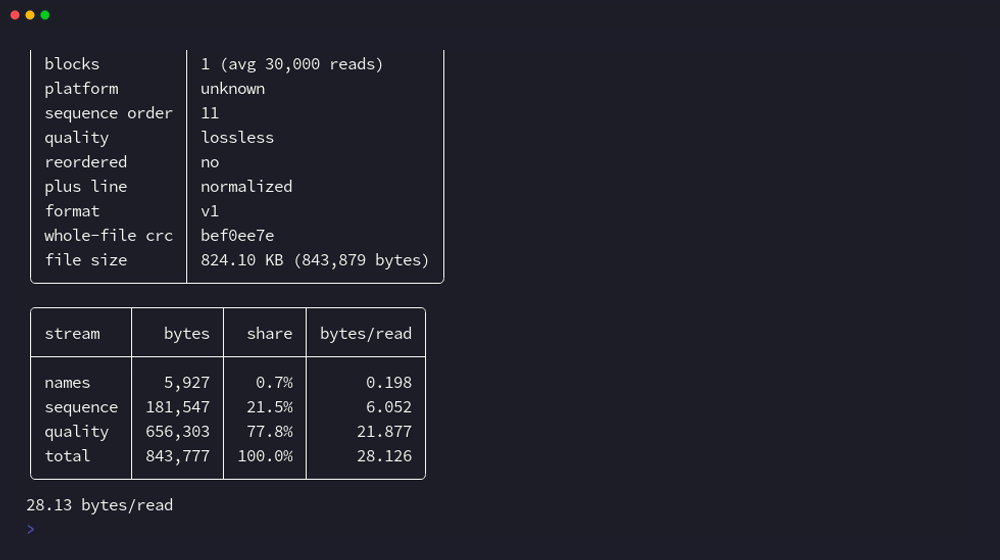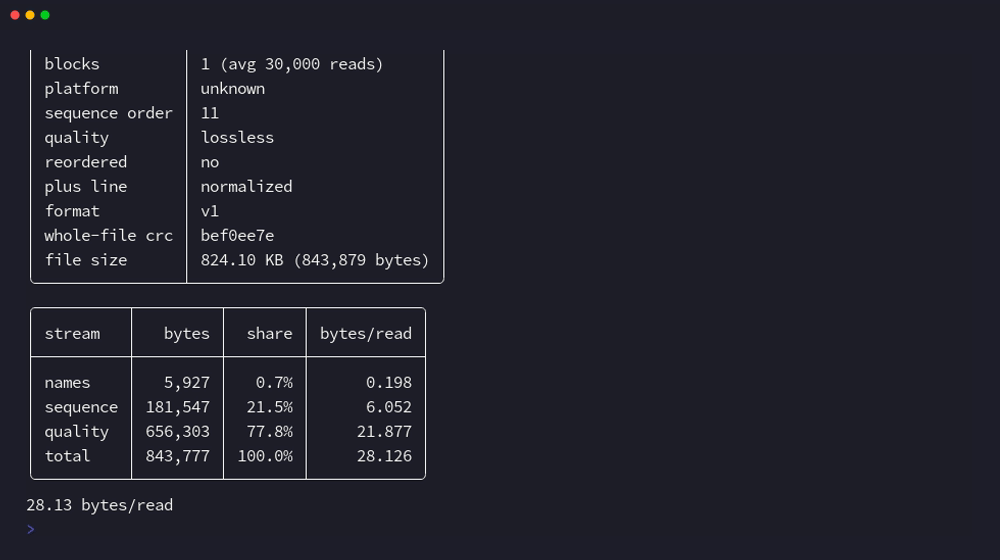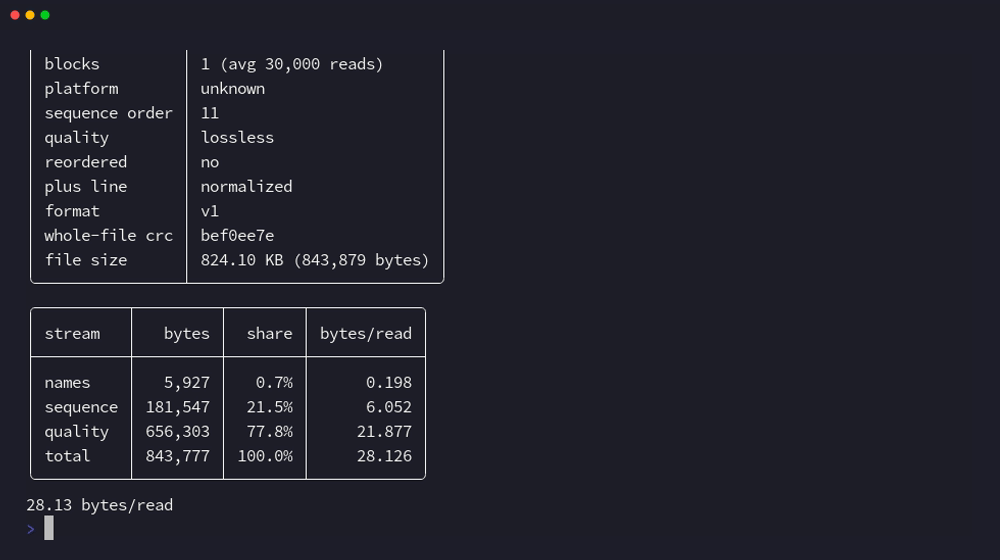
By default info prints a human-readable report of two tables (metadata and
per-stream sizes) from the header and footer index alone — it does not decode any
payload. Pass --tsv or --json for machine-readable output; the two are
mutually exclusive.
Give several files, or a directory (scanned recursively for *.fqxv), to report
a batch — see Reporting a batch.
Arguments
| Argument | Description |
|---|---|
<INPUTS>... |
Input .fqxv file(s), or a directory scanned for *.fqxv. |
Options
| Option | Description |
|---|---|
-s, --stats |
Also report content statistics — read-length spread, base composition, GC%, and the quality distribution. This decodes the whole archive, so it costs a full decompress. |
--tsv |
Emit a single machine-readable TSV line instead of the human report (a batch prepends a file column and prints one row per archive). |
--json |
Emit a JSON object instead of the human report (a batch emits an array of them). |
--threads <N> |
Worker threads (0 = all cores); only relevant with --stats. |
Example
fqxv info sample.fqxv
sample.fqxv
╭────────────────┬──────────────────────────────╮
│ property       │ value                        │
├────────────────┼──────────────────────────────┤
│ layout         │ paired (group size 2)        │
│ reads          │ 20,000                       │
│ spots          │ 10,000                       │
│ blocks         │ 1 (avg 20,000 reads)         │
│ platform       │ Illumina                     │
│ sequence order │ 11                           │
│ quality        │ lossless                     │
│ reordered      │ no                           │
│ plus line      │ normalized                   │
│ format         │ v1.0                         │
│ whole-file crc │ a1b2c3d4                     │
│ file size      │ 1.01 MB (1,058,497 bytes)    │
╰────────────────┴──────────────────────────────╯
╭──────────┬───────────┬────────┬────────────╮
│ stream   │     bytes │  share │ bytes/read │
├──────────┼───────────┼────────┼────────────┤
│ names    │    76,416 │   7.2% │      3.821 │
│ sequence │   455,180 │  43.0% │     22.759 │
│ quality  │   526,867 │  49.8% │     26.343 │
│ total    │ 1,058,463 │ 100.0% │     52.923 │
╰──────────┴───────────┴────────┴────────────╯
52.92 bytes/read
Machine-readable output
--tsv emits a fixed header line plus one data line. The columns are stable
(new fields are only ever appended), so it is safe to parse in scripts and the
benchmark harness. Note that format_version here is the numeric packing
(major << 8) | minor — 256 for format 1.0 — not the v1.0 string the human
report prints:
fqxv info sample.fqxv --tsv
file_size   reads   blocks  group_size  seq_order   quality_binning reordered   names_bytes seq_bytes   qual_bytes  platform    format_version  whole_file_crc
1058497 20000   1   2   11  0   0   76416   455180  526867  illumina    256 a1b2c3d4
With --stats, five more columns are appended
(bases min_len max_len gc_fraction mean_quality).
--json emits a single object with the same facts plus derived fields
(percentage shares, bytes_per_read, and human labels). spots and
bytes_per_read are omitted for single-end or empty archives:
fqxv info sample.fqxv --json
{
  "file": "sample.fqxv",
  "file_size": 1058497,
  "file_size_human": "1.01 MB",
  "platform": "illumina",
  "reads": 20000,
  "spots": 10000,
  "blocks": 1,
  "layout": "paired",
  "group_size": 2,
  "sequence_order": 11,
  "quality": "lossless",
  "quality_binning": 0,
  "reordered": false,
  "read_order_preserved": true,
  "plus_normalized": true,
  "streams": {
    "names": { "bytes": 76416, "pct": 7.2, "per_read": 3.821 },
    "sequence": { "bytes": 455180, "pct": 43.0, "per_read": 22.759 },
    "quality": { "bytes": 526867, "pct": 49.8, "per_read": 26.343 },
    "total": { "bytes": 1058463, "pct": 100.0, "per_read": 52.923 }
  },
  "bytes_per_read": 52.92,
  "format_version": 256,
  "whole_file_crc": "a1b2c3d4"
}
With --stats, the object gains a nested stats block (read/base counts, length
spread, GC fraction, base composition, mean quality, and a quality histogram).
Content statistics (--stats)
--stats decodes the whole archive and appends a content-statistics table plus a
quality-distribution histogram (read-length spread, GC%, per-base composition,
mean quality). Because it fully decodes, it costs a decompress rather than the
default header/footer-only read.
fqxv info sample.fqxv --stats
Reporting a batch
Several inputs — or a directory, scanned recursively for *.fqxv — report one
entry per archive. The human output prints each archive's tables under its
filename; the machine-readable forms stay keyed by file, so a batch is directly
loadable:
fqxv info archives/ --tsv
file    file_size   reads   blocks  group_size  seq_order   quality_binning reordered   names_bytes seq_bytes   qual_bytes  platform    format_version  whole_file_crc
archives/reads.fqxv 43564   400 1   1   11  0   0   6577    10492   26310   illumina    256 d27290bb
archives/sample.fqxv    79192   800 1   2   11  0   0   7488    20669   50840   illumina    256 249666e0
--json emits an array of the same per-file objects.
Fields
| Field | Meaning |
|---|---|
layout |
single-end, paired, or grouped xG (single-cell), followed by the group size in the human report. |
reads / spots |
Total reads; spots = reads / group size (paired/grouped only). |
blocks |
Number of independently-coded blocks. |
platform |
Sequencing platform (Illumina, Oxford Nanopore, PacBio, MGI/BGI, or unknown), detected from read names at compress time. Override with compress --platform. |
sequence order |
Order of the sequence context model. |
quality |
lossless or the lossy binning level used. |
reordered |
Whether reads were clustered/reordered for a better ratio. |
read order |
For reordered archives, whether the original order is restored. |
plus line |
Whether the + line was normalized. |
format |
On-disk container format version, vMAJOR.MINOR (currently v1.0). |
whole-file crc |
Stored whole-file CRC-32C (hex); the value verify recomputes. Shown as — (and omitted from --json) for a globally reordered archive, which carries per-frame CRCs instead. |
names / sequence / quality |
Compressed bytes per stream, with share of the three-stream total. |