🗜️ fqxv


A fast, reference-free FASTQ archiver, written in Rust. fqxv compresses each part of a FASTQ record with a codec
tuned to it — a context model for quality, an order-k model for sequence, a
positional tokenizer for names — and composes them into one parallel,
block-based container.
The on-disk format is stable at 1.0
Archives written today stay readable by later releases. A reader accepts its own format major version and tolerates newer minors, skips additions it can safely ignore (a non-critical header extension record), and refuses the ones it cannot — a required-feature bit at header-read, or a per-block codec it does not know when it reaches that block — with an "upgrade fqxv" error rather than misreading. Compatibility fails loudly, never silently. The format version is independent of the crate version: the format is at 1.0 while the crates are still 0.x. See the evolution policy.
Every archive is deterministic (byte-identical regardless of thread count) and
carries per-block and per-stream checksums; compress --verify re-decodes a
freshly written archive and confirms it round-trips before you trust it.
Why fqxv
- Reference-free & lossless — no genome required; read name + description,
sequence, and quality are preserved exactly (the redundant
+line is normalized to a bare+, as SPRING and fqz_comp do). - Strong ratios — clean-room implementations that match or beat the C reference tools stream-for-stream on most of the benchmark panel (see Benchmarks).
- Parallel — blocks compress and decompress across cores with
rayon; output is deterministic regardless of thread count. - Paired & single-cell aware — interleave R1/R2 (and 10x I1/I2) into one archive; split them back out, or stream interleaved to an aligner.
- One crate per algorithm — every codec is an independently usable, independently published Rust crate.
Install
pixi add bioconda::fqxv                          # Bioconda
conda install -c conda-forge -c bioconda fqxv    # or conda / mamba
uv pip install fqxv                              # read-only Python package
Prebuilt binaries, BioContainers Docker/Singularity images and Nextflow usage are all in Installation.
Quick look
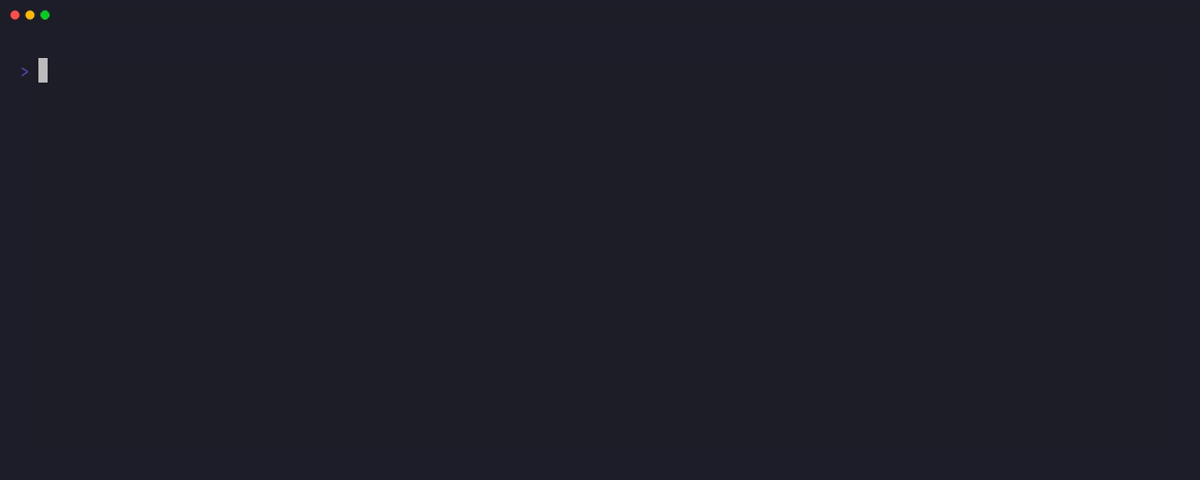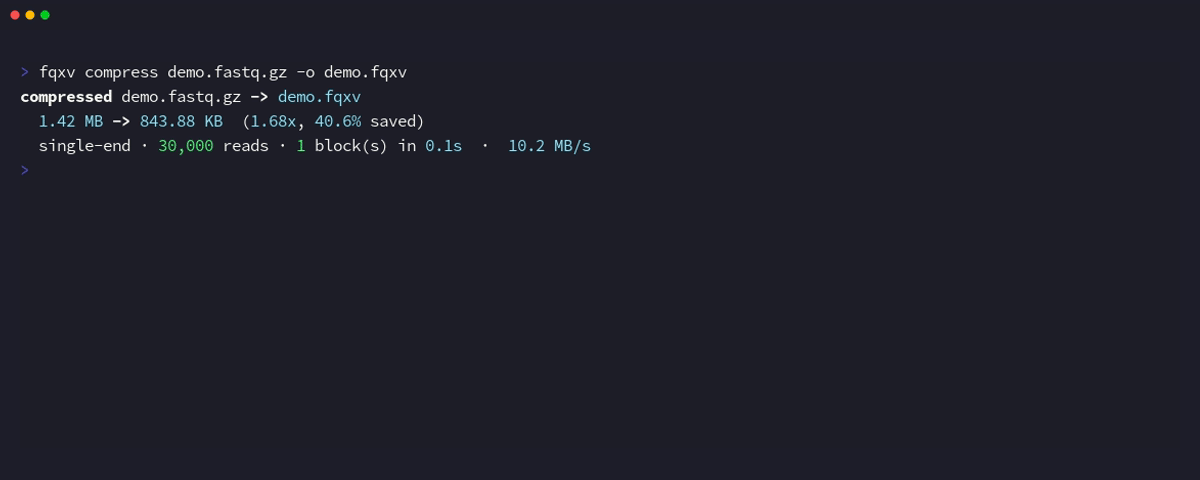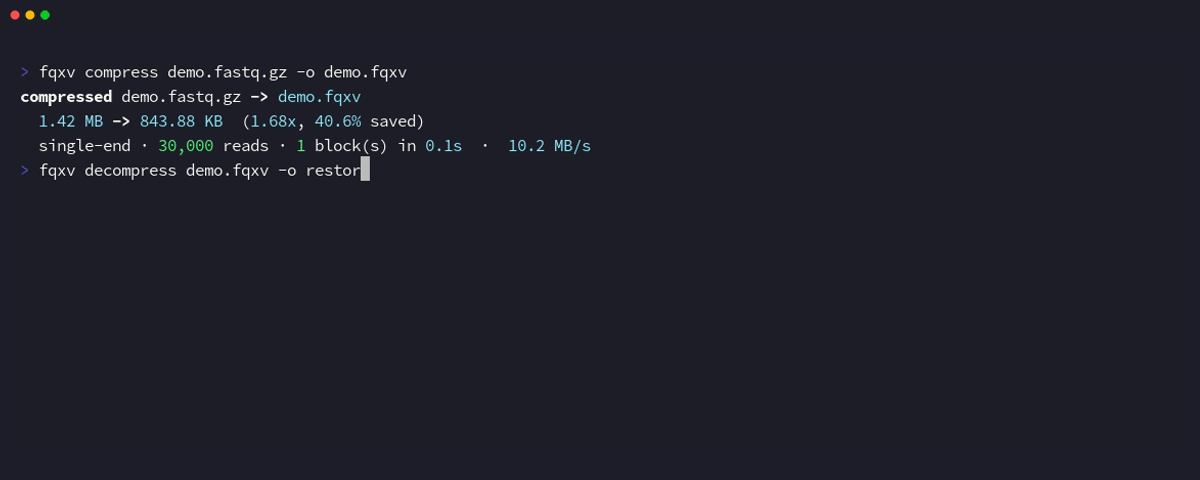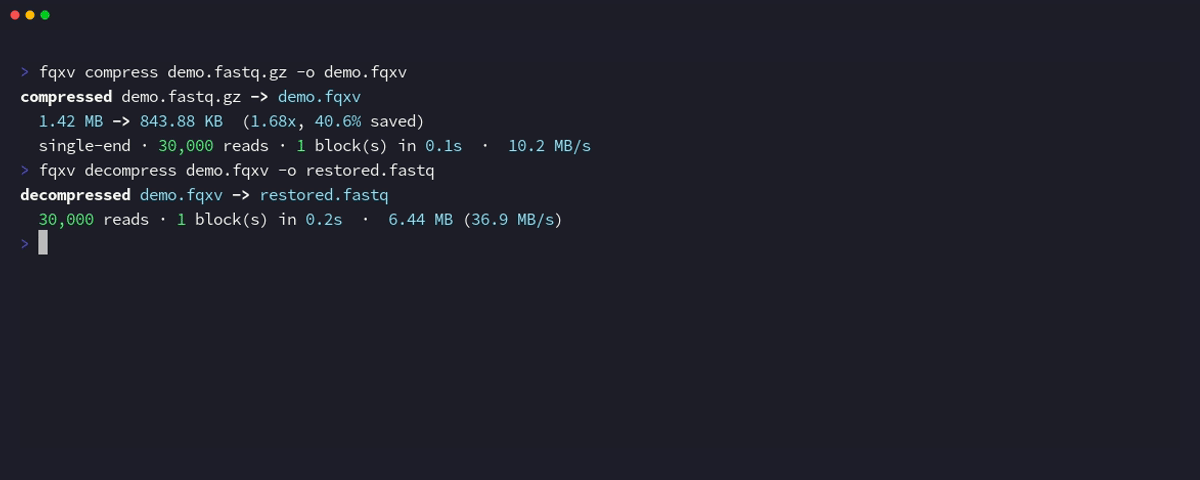
# single-end (gzip input auto-detected; -o defaults to reads.fqxv)
fqxv compress reads.fastq.gz
fqxv decompress reads.fqxv -o reads.fastq

# paired-end / single-cell: one archive, split back or stream to an aligner
fqxv compress sample_R1.fq.gz sample_R2.fq.gz -o sample.fqxv
fqxv decompress sample.fqxv --split out            # out_R1.fastq.gz, out_R2.fastq.gz
fqxv decompress sample.fqxv -Z | bwa mem -p ref.fa -  # interleaved, raw, to stdout

fqxv info sample.fqxv                              # layout, reads, per-stream sizes (--tsv/--json)
How it works
A FASTQ record splits into three streams that compress very differently, and
fqxv gives each its own codec:
| Stream | Codec crate | Approach |
|---|---|---|
| Quality scores | fqxv-fqzcomp |
context model (prev-quals + position), range-coded |
| Sequence | fqxv-seq |
order-k adaptive base model over a 2-bit alphabet |
| Read names | fqxv-tokenizer |
positional tokens (match / delta / literal), rANS-coded |
The entropy backends — fqxv-rans (rANS Nx16, with AVX2 and AVX-512 order-0
paths) and fqxv-range (a Subbotin range coder) — are themselves standalone
crates.
Where to go next
- Installation — Bioconda, containers and Nextflow, prebuilt binaries, building from source, and the crates
- Quick Start — compress, inspect, decompress
- CLI Reference — every command and flag
- Python API — read
.fqxvarchives from Python - Design — codecs, container format, and reordering
- Long-read support — ONT/PacBio: the cross-read sequence codecs and where fqxv stands against CoLoRd
- Benchmarks — how fqxv stacks up against gzip, fqz_comp, SPRING
- Format comparison — capabilities and guarantees vs
gzip/zstd, SPRING, CoLoRd, CRAM, and
.sra - Acknowledgments — the prior work fqxv builds on