fqxv decompress
Restore FASTQ from a .fqxv archive — to a file, to split mate files, or
streamed to stdout for a pipe. You must choose exactly one destination
(-o, --split, or -Z); a bare decompress with none errors rather than
flooding the terminal.
Usage
fqxv decompress <INPUT> (-o <OUTPUT> | --split <PREFIX> | -Z)
Arguments
| Argument | Description |
|---|---|
<INPUT> |
Input .fqxv file, or - to stream from stdin (see Reading a remote archive). |
Options
| Option | Description |
|---|---|
-o, --output <PATH> |
Interleaved FASTQ output file. A .gz extension writes block-gzip (BGZF); any other extension writes plain FASTQ. -o - streams to stdout. |
-Z, --stdout |
Stream interleaved, always-raw FASTQ to stdout (for piping into an aligner). Required to write to stdout. |
--split <PREFIX> |
Restore separate per-spot files: <PREFIX>_R1.fastq.gz … _R<G>.fastq.gz (block-gzip by default), or the archive's recorded slot labels if it has them. |
--mate-style <auto\|r\|num> |
--split labels: auto → the archive's recorded slot labels, else _R1,_R2,… (default); r → always _R1,_R2,…; num → always _1,_2,…. |
--no-gzip |
Write plain .fastq for --split instead of the default .fastq.gz. |
--fasta |
Write FASTA instead of FASTQ. The quality stream is skipped, not decoded — ~12× faster on long-read archives, ~1.3–1.6× single-threaded on short-read Illumina — for k-mer counters, classifiers, and aligners that ignore base qualities. See below. |
--recover |
Best-effort decode of a corrupted archive: skip blocks that fail their CRC and emit the rest. See below. |
-f, --force |
Overwrite output FASTQ file(s) if they already exist. By default an existing -o file or --split mate file is left untouched and the command errors before decoding. Ignored when writing to stdout (-Z / -o -). |
--threads <N> |
Worker threads (0 = all cores). |
--output, --split, and --stdout are mutually exclusive, as are --split and
--recover; --fasta cannot be combined with --split or --recover.
--mate-style / --no-gzip apply only with --split.
Examples
# to a file (plain FASTQ)
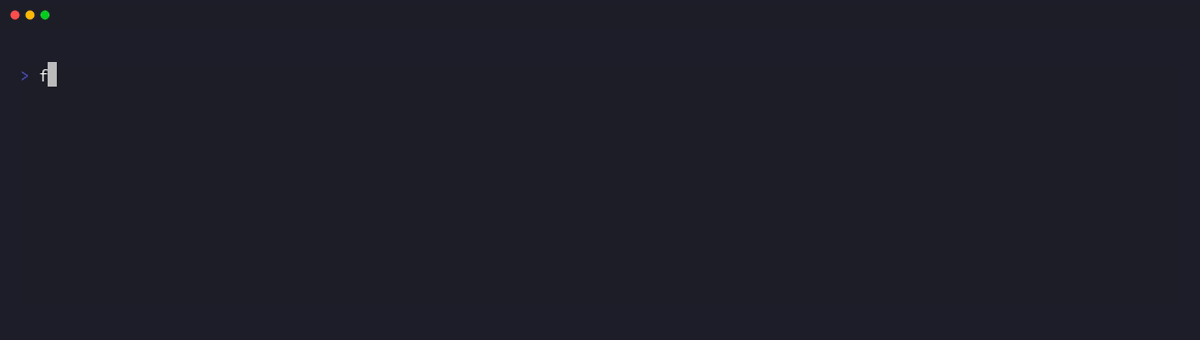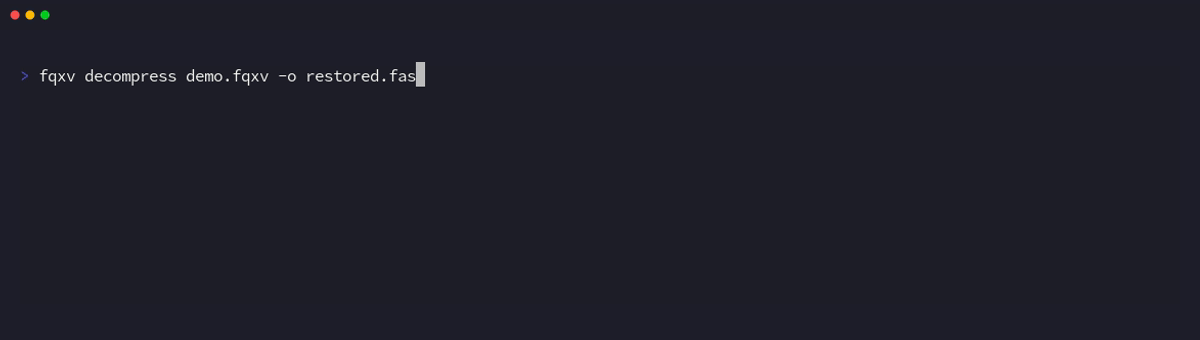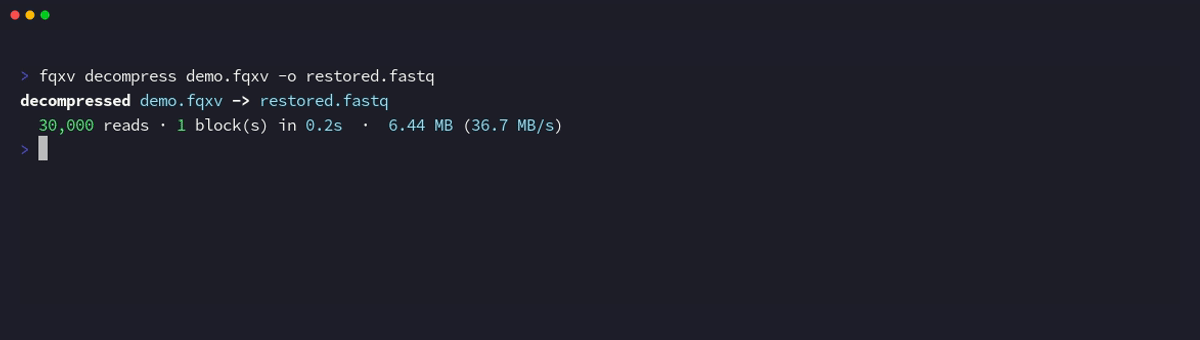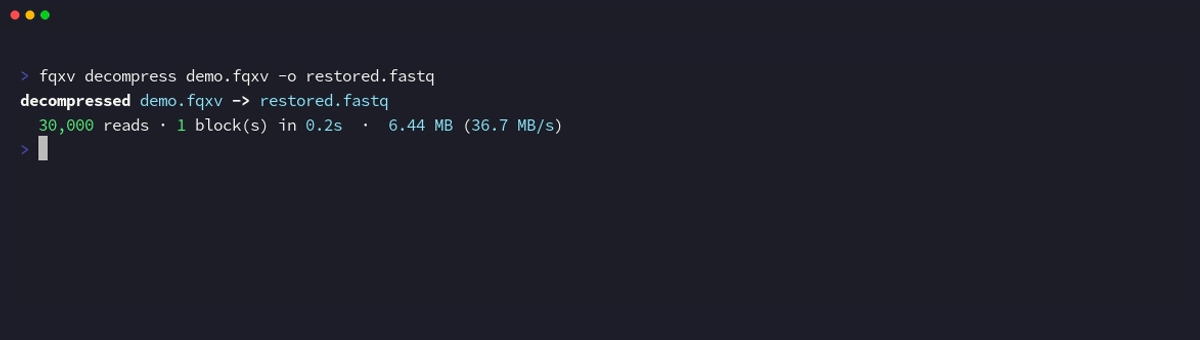
fqxv decompress reads.fqxv -o reads.fastq

# to a block-gzip file (BGZF, indexable by tabix/samtools)
fqxv decompress reads.fqxv -o reads.fastq.gz

# stream interleaved to an aligner (no temp files) — -Z is required for stdout
fqxv decompress sample.fqxv -Z | bwa mem -p ref.fa -
fqxv decompress sample.fqxv -Z | bowtie2 --interleaved - -x idx

# split a paired / single-cell archive back into its files (BGZF by default)
fqxv decompress sample.fqxv --split out
#   -> out_R1.fastq.gz, out_R2.fastq.gz   (paired)
#   -> out_R1/_R2/_I1/_I2.fastq.gz        (single-cell, recorded slot labels)
#   -> out_R1.fastq.gz ... out_R4.fastq.gz (no labels recorded: positional)

# plain, numbered mate files
fqxv decompress sample.fqxv --split out --no-gzip --mate-style num
#   -> out_1.fastq, out_2.fastq

# sequence-only FASTA, straight into a k-mer counter — the quality stream is
# never decoded (~12x faster on long-read archives)
fqxv decompress reads.fqxv --fasta -Z | kmc -fa ...
Reading a remote archive
decompress reads - from stdin and decodes it as it arrives (it only reads
forward and stops at the archive's terminator frame), so an archive in S3 or behind
a URL is read by piping a transfer tool into it. The tool owns the download — auth,
retries, resume, multipart — and fqxv just decodes the stream; no fqxv network
dependency, no temp file:
# S3 with the AWS CLI — uses your normal credentials (IAM instance/task role,
# SSO, env vars, or ~/.aws profile); no fqxv-specific config
aws s3 cp s3://my-bucket/reads.fqxv - | fqxv decompress - -Z | bwa mem -p ref.fa -

# a presigned S3 URL, or any HTTP(S) endpoint
curl -fsSL "https://my-bucket.s3.amazonaws.com/reads.fqxv?X-Amz-Signature=…" \
  | fqxv decompress - -Z | bowtie2 --interleaved - -x idx

# Google Cloud Storage
gsutil cat gs://my-bucket/reads.fqxv | fqxv decompress - -o reads.fastq
A truncated transfer is caught (the decode hits EOF before the terminator frame and
errors) rather than yielding a silent short prefix. --recover and --split need a
seekable file — a stream can't be rewound — so download to a file first for those,
or decode interleaved (-Z) and split downstream.
For programmatic access, the Python bindings read a remote archive without the CLI —
whole-file streaming (fqxv.open(response) / fqxv.remote.stream(url)) or fetching
just one column over HTTP range requests (fqxv.remote.RemoteArchive). See the
Python bindings.
Notes
- For a grouped archive, the
-o/-Z(interleaved) output emitsm0, m1, …per spot — exactly the interleaved layout aligners expect with-p/--interleaved. --splitreads the archive's group size from its header and creates that many output files, in the original input order.- Newer archives also record each member's original slot label
when it could be derived from the input file names, and
--mate-style auto(the default) restores those names. This matters for runs whose read slots are empty over part of the run: their per-slot files are numbered by original slot and can have gaps (_2and_4, no_1/_3), so positional naming would silently renumber them to_1/_2. Pass--mate-style rornumto force positional names, and note that older archives (and inputs without a recognizable slot token) have no labels to restore and always number positionally. - BGZF outputs use a multithreaded block-gzip encoder on the
--threadspool, so the resulting.gzfiles are valid gzip and additionally support random access via a.gziindex (bgzip/samtools/tabix).
Integrity
Every decode verifies, per block, the stored CRC-32C (before decode) and an
xxh3-64 digest of the decoded content (after decode), so on-disk corruption or a
codec that decodes valid bytes into wrong output is caught rather than emitted. In
addition, a file decompress reads the footer's authoritative read count up front
and confirms the decode produced exactly that many reads — a truncated archive
(which also loses its footer) is rejected instead of yielding a short, silent
prefix. Use --recover to intentionally salvage
a damaged archive.
Sequence-only decode (FASTA)
Many analysis tools — k-mer counters, taxonomic classifiers, aligners run without
base-quality awareness — never look at quality scores. --fasta emits single-line
>name + sequence records and seeks past the quality stream without decoding
it, which makes the archive directly usable as sequence input at the quality
stream's full decode cost saved. The win tracks where decode compute sits: on
long-read archives the sequence-conditioned quality model dominates, and --fasta
measured ~12× faster (ONT E. coli, 1 and 16 threads); on short-read Illumina
the sequence context model shares the cost, for ~1.3–1.6× single-threaded
(NovaSeq/MiSeq) — at high thread counts short-read decode is bounded by the serial
output path, so the saving shows up as ~35% less CPU rather than less wall time.
fqxv decompress reads.fqxv --fasta -o reads.fasta
fqxv decompress reads.fqxv --fasta -Z | kmc -fa @/dev/stdin out workdir
Records come back in the same order (and for grouped archives, the same
interleaving) a full decompress would emit. Integrity: every stream that is
decoded keeps its per-block content-digest check; the skipped quality stream's
digest cannot be checked (its content is never reconstructed), so fqxv verify
remains the tool for whole-archive integrity. Programmatic equivalents:
decompress_fasta and the stream-selective decompress_records_select /
RecordReader::with_selection (names / sequence / quality, each independently
selectable) in the Rust API.
Recovering a corrupted archive
If fqxv verify reports an archive as corrupt, --recover salvages
everything that is still intact instead of failing outright:
fqxv decompress --recover damaged.fqxv -o recovered.fastq
Because blocks are independent and the footer's row-group index records each block's absolute offset, a block that fails its CRC (or won't decode) is skipped by seeking straight to the next one — one bad byte costs a single row group, not the whole file. Each skipped block is logged with the reads lost, and a summary is printed at the end:
warning: recovered 812 block(s), skipped 3 corrupt block(s) — 30000 read(s) lost
Notes and limits:
- Output is interleaved FASTQ, exactly like a normal
decompress;--recovercannot be combined with--split. - Recovery applies to the plain layout only. A globally-clustered
reordered archive is all-or-nothing
(its streams are mutually dependent) and returns an error directing you to a
plain
decompress. - A lost footer is handled. When the footer index is unreadable — the common truncated-download case, which also takes the trailing blocks with it — recovery falls back to scanning for each block's sync marker, so it resynchronizes past a corrupt length prefix or a bad block and still recovers every intact block. (In that mode the per-block read counts are gone, so the "reads lost" tally is unavailable, but the recovered reads are all emitted.)